In manufacture
2 Neural Processing Units
AI models run on the device itself: thousands of multiply-accumulate units work in parallel, with memory right beside them.
Trijal P G · Chennai, India
Founder & CEO of Qynetic Labs. Hardware designer.
--:-- in Chennai27 public repos
02The board
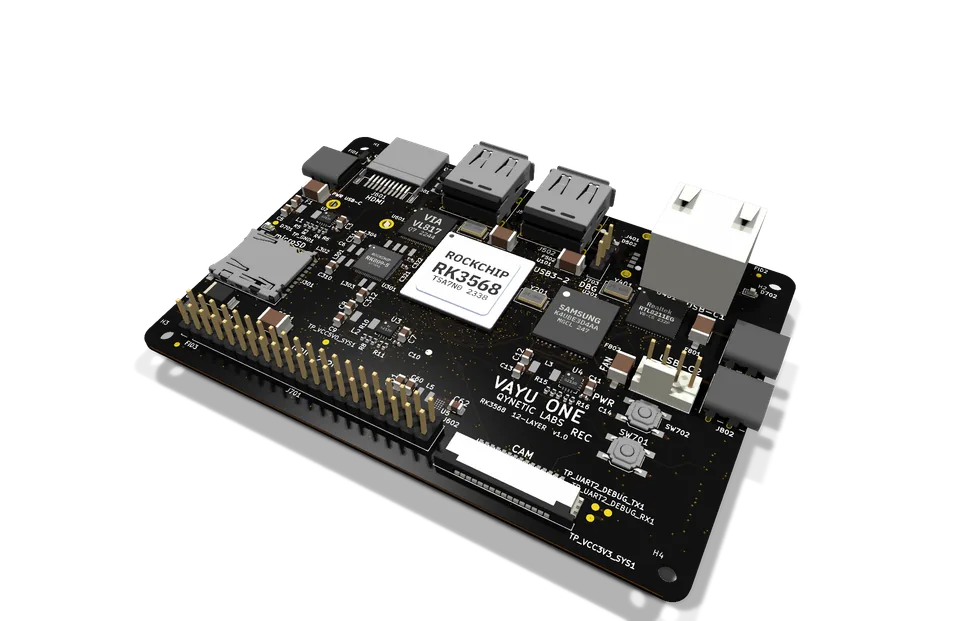
A Rockchip RK3568 computer I designed in KiCad. 12 layers, 182 parts, zero unrouted.
03Silicon
Two NPUs in manufacture, and a TPU that already ships inside Vayu Pro and Ultra.
In manufacture
AI models run on the device itself: thousands of multiply-accumulate units work in parallel, with memory right beside them.
Manufactured · shipping
Built for cost-efficient inference, inside and .
Tap a chip to open it · drag to turn it
04The plan
Qynetic Labs is building India’s full-stack edge-AI platform, ending in our own QChip silicon.
05Builds
Solvers, security boxes, sensors and agents. Tap one for the full story.
06Journey
B.E. Computer Science (Cyber Security)Chennai Institute of Technology · 2028
Qualified for the IIT Madras B.S. in Data Science
07Live
08Say hello
Founder’s office, product, hardware or edge AI: if you’re working on something real, I’d like to hear about it.
trijalpg@qyneticlabs.comI’m Trijal, founder & CEO of Qynetic Labs, an edge-AI hardware startup in Chennai. Hardware, software, security, and the plan that pays for them.
12 layers. 182 parts. Zero unrouted.
Qynetic Labs makes edge-AI computers: AI that runs on the device, not in the cloud. Our own hardware, OS, SDKs and fleet tools, with public-sector channels and local support.
Founded 2024 · Private Limited since June 2026
From a developer board to a 434 TOPS edge server, all running QyneticOS and the same SDK. Tap a board for its specs.
In manufacture
An NPU runs AI models on the device itself. Thousands of multiply-accumulate units do the maths in parallel, while on-chip memory keeps weights and data close, so inference is fast and light on power.
Drag to rotate · tap to open
Inside the NPU die
Manufactured · in the Vayu lineup
Built for cost-efficient inference. A TPU is designed around matrix multiplication, the core operation of every neural network: data and weights flow through a grid of processing cells in lockstep, so each value is reused many times instead of being fetched again.
Drag to rotate · tap to open
How the TPU computes
B.E. Computer Science & Engineering (Cyber Security) · Chennai Institute of Technology · 2028 · IIT Madras B.S. (qualified)
Contributions per month
Languages by code size
Hiring for a founder’s office, product, hardware or edge-AI role? Building something at the edge? I’d like to hear from you.
Personal: trijalgunaseelan13@gmail.com